Give old hardware a second life.
That workstation in the comms room, the server that got mothballed when you moved to the cloud. A lot of it can run a useful model with the right card and a bit of work.
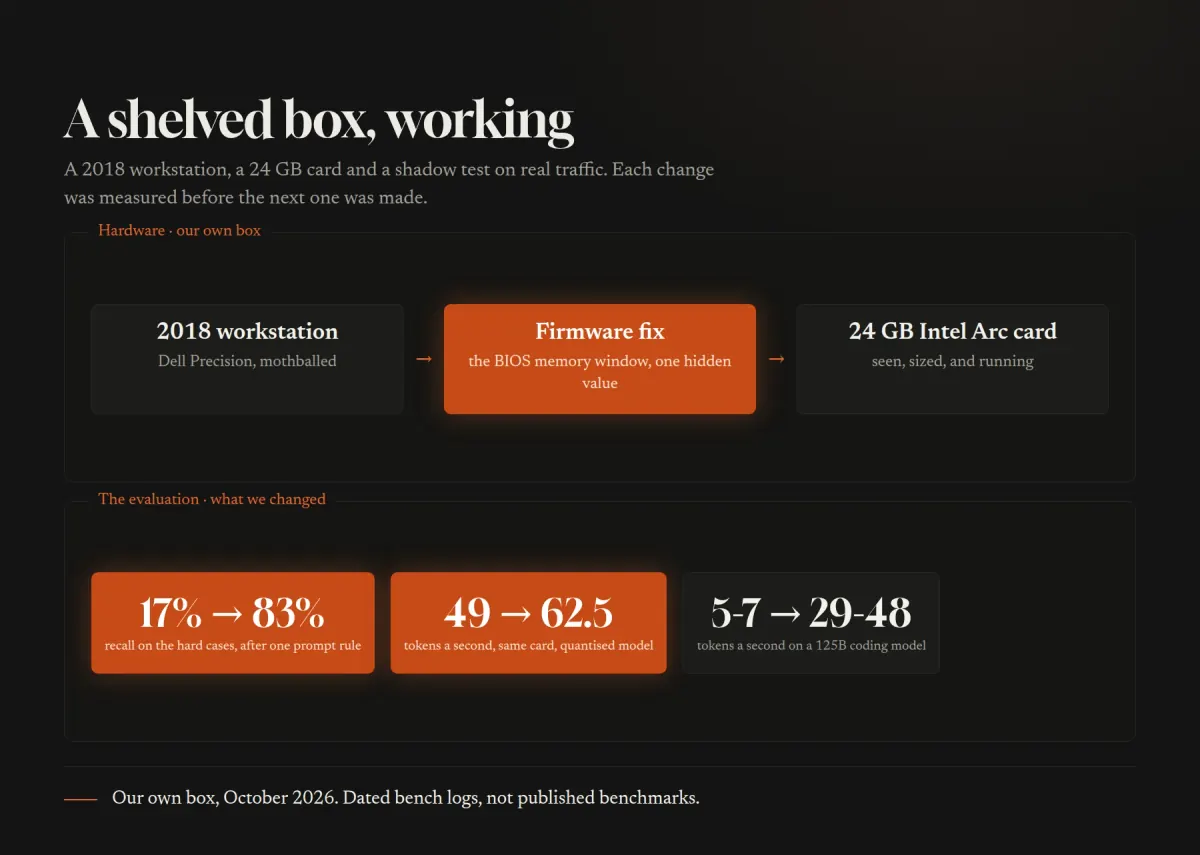
Our own AI server is a 2018 Dell Precision workstation. It wouldn't see its new 24 GB graphics card at all: the BIOS gave the card too small a window of memory, and Dell offers no setting to change it. We found the hidden firmware value that fixes it, about ten minutes at the machine, and published the fix so others can use it.
Then the tuning. Picking the right quantised model for the card moved one model from 49 to 62.5 tokens a second on the same hardware. On Intel Arc we wrote our own model server to get multiple users served at once: about 60 tokens a second for one person, about 117 across three. (Our own box, October 2026.)
49 → 62.5